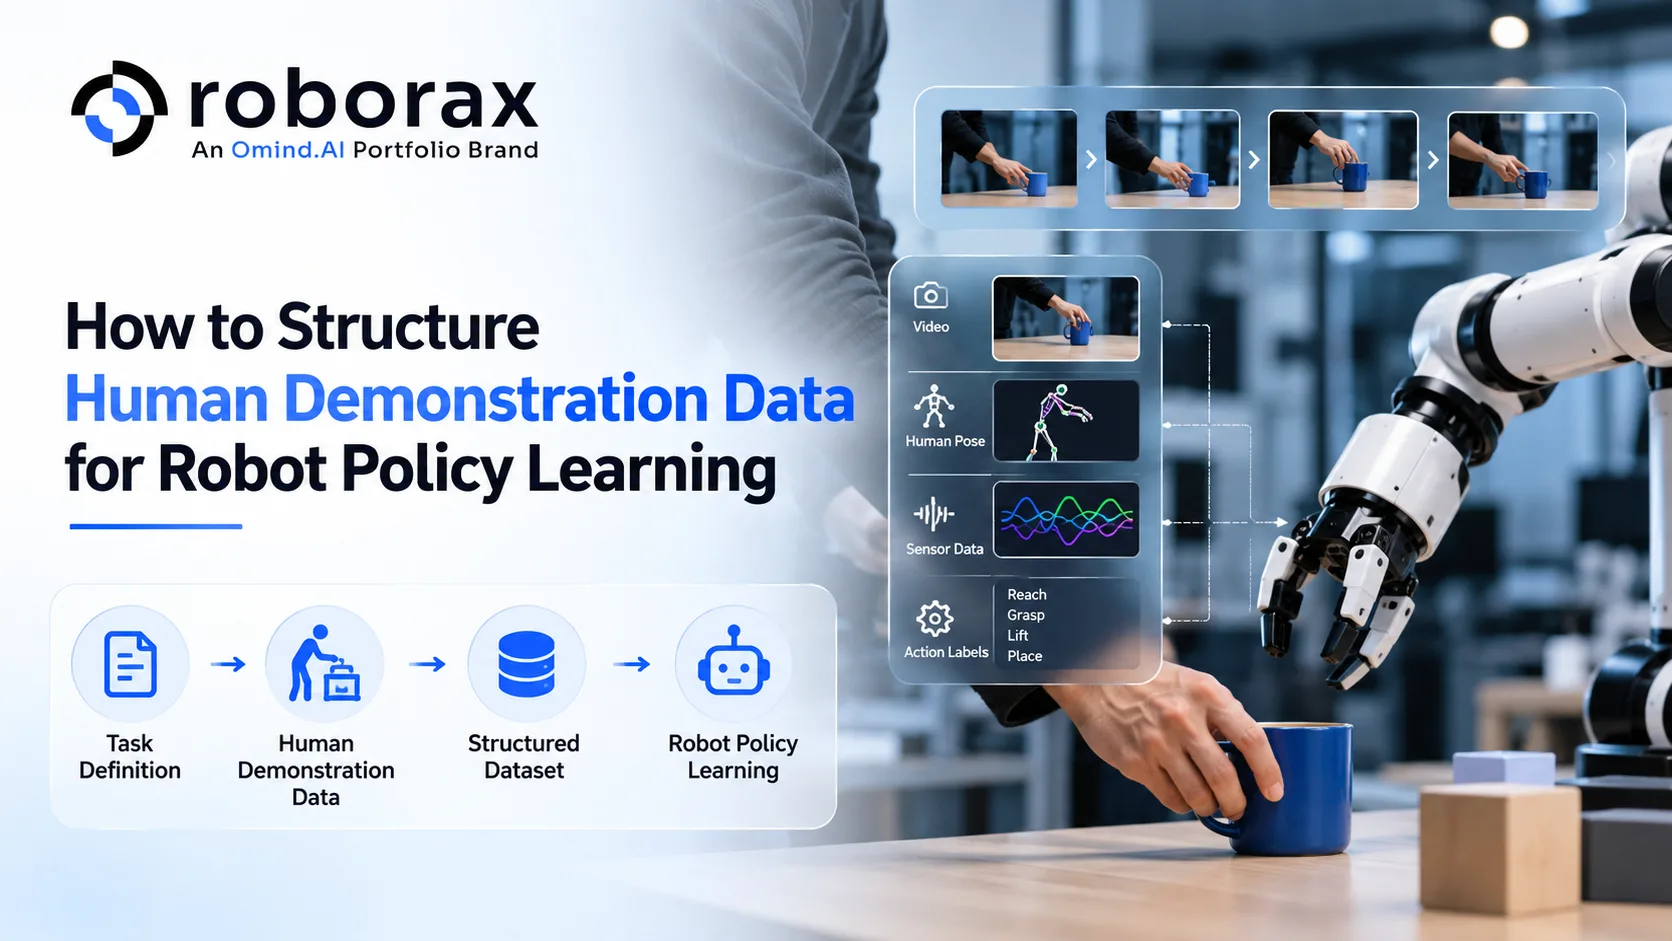
Robot policy learning enables robots to learn how to perform tasks by observing demonstrations, interpreting sensory inputs, and translating experience into actions. However, successful learning depends on more than collecting large volumes of demonstrations. The data must be structured so that models can understand the relationship between observations, actions, task objectives, and environmental conditions.
Well-organized Human Demonstration Data for Robot Learning helps robotics teams train policies that generalize across objects, environments, and task variations. From recording human movements to aligning multimodal sensor streams, every stage of dataset preparation influences the reliability of the resulting policy.
For organizations developing embodied AI systems, a structured approach to robotic training data creates a foundation for scalable experimentation, evaluation, and deployment. This guide explores the essential components of a demonstration dataset and the best practices for preparing it for robot policy learning.
1. Define the Task and Learning Objective
Before collecting demonstrations, clearly define what the robot must accomplish. A broad instruction such as “organize the workspace” may involve several subtasks, including identifying objects, reaching for them, grasping them, and placing them in designated locations.
Break complex tasks into measurable objectives and define the expected inputs, actions, and success conditions for each task.
A well-defined task specification should include:
- Task description: The intended outcome and relevant environmental conditions.
- Initial state: Object positions, robot configuration, and scene characteristics.
- Action requirements: The movements or control commands needed to complete the task.
- Success criteria: Observable conditions that indicate task completion.
- Failure conditions: Events such as dropped objects, collisions, or unsuccessful grasps.
These definitions establish a consistent framework for collecting demonstrations and evaluating policy performance. They also help ensure that demonstrations recorded by different operators remain comparable.
2. Organize Demonstrations Into Consistent Data Units
A useful demonstration dataset should have a predictable structure. Each demonstration can be represented as a sequence of time-aligned observations, actions, and contextual information.
At the dataset level, organize records into three logical layers:
Dataset level: Contains task definitions, collection protocols, robot specifications, and dataset version information.
Episode level: Stores individual demonstrations, including episode identifiers, initial conditions, operator information where appropriate, and task outcomes.
Time-step level: Records observations, actions, timestamps, and relevant state information throughout an episode.
For example, a robot learning to pick up a cup may receive camera images and joint positions at each time step, alongside the corresponding end-effector movement or control command.
This hierarchical structure makes demonstrations easier to retrieve, compare, validate, and reuse across different training experiments. It also simplifies the process of identifying incomplete episodes or investigating performance failures.
3. Align Observations, Actions, and Timestamps
Temporal synchronization is one of the most important requirements for policy learning. A demonstration may contain multiple camera feeds, joint-state measurements, gripper commands, and force or torque readings. If these signals are misaligned, the model may learn incorrect relationships between what it observes and the actions it should execute.
To prevent this problem, robotics teams should:
- Use a consistent timestamp convention across recording systems.
- Synchronize camera frames with robot states and control commands.
- Record sensor frequency, missing frames, and communication delays.
- Validate whether commanded actions correspond to the robot's executed movements.
- Preserve original timestamps during preprocessing and resampling.
For instance, when a human demonstrates grasping an object, the recorded visual observation must correspond closely to the robot state and gripper command associated with that moment. Proper alignment improves the reliability of training examples and supports accurate reconstruction of action sequences.
4. Standardize Action Representation
Human demonstrations can be captured through teleoperation, motion capture, wearable sensors, or direct human observation. However, different collection methods may produce incompatible action representations.
A policy trained using joint-space commands cannot automatically interpret end-effector movements recorded in Cartesian coordinates without suitable conversion or adaptation.
Define the action schema before large-scale data collection. Depending on the robot and learning objective, actions may include:
- Joint positions, velocities, or torques.
- End-effector position and orientation.
- Gripper opening and closing commands.
- Relative movement commands or absolute target positions.
- Control duration and execution status.
Document coordinate frames, measurement units, rotation conventions, and control frequencies. Where human movements must be translated into robot actions, validate the mapping against the target embodiment.
This consistency makes robotic training data easier to combine across collection sessions and reduces errors during model training and deployment.
5. Add Task Labels and Contextual Metadata
Raw trajectories explain what happened, but contextual labels help learning systems understand the purpose and outcome of a demonstration.
Useful metadata includes task instructions, object categories, scene conditions, subtask boundaries, operator identifiers where appropriate, and success or failure labels. Event-level annotations can identify meaningful transitions such as object contact, grasp completion, object release, or task interruption.
For example, a pick-and-place episode can be segmented into reaching, grasping, lifting, transporting, and placing phases. These labels can support task analysis, error diagnosis, and learning approaches that benefit from structured action sequences.
Use a consistent annotation schema and maintain a version history whenever labels or definitions change. This ensures that training teams can trace model behavior back to the data and annotation rules used in a particular experiment.
6. Build Diversity and Failure Examples Into the Dataset
A policy may perform well in familiar conditions but struggle when objects, lighting, camera angles, or starting positions change. A structured dataset should therefore capture meaningful variations rather than simply maximizing demonstration counts.
Include different object shapes, sizes, textures, spatial arrangements, and environmental conditions relevant to deployment. Collect demonstrations from multiple operators when appropriate, while maintaining consistent task definitions and recording standards.
Failure cases are equally valuable. Examples of unsuccessful grasps, object slippage, interrupted movements, and recovery attempts can help teams identify weaknesses and develop more robust learning strategies.
However, failed demonstrations should be clearly labeled rather than mixed indiscriminately with successful trajectories. Their use should match the learning objective, whether it involves imitation learning, failure prediction, or reinforcement learning.
7. Implement Quality Assurance and Dataset Governance
Before training begins, validate the dataset for completeness, consistency, and technical integrity.
A practical quality assurance pipeline should check:
- Completeness: Required observations, actions, and metadata are present.
- Synchronization: Sensor streams follow the expected timing tolerances.
- Validity: Values are within physically plausible ranges.
- Annotation accuracy: Task labels and episode boundaries follow the defined schema.
- Outcome verification: Success, failure, and interruption labels are supported by recorded evidence.
- Reproducibility: Dataset versions, robot configurations, and preprocessing steps are documented.
Maintain separate training, validation, and test splits, taking care to avoid leakage between closely related demonstrations. Where possible, evaluate generalization using distinct scenes, objects, or collection sessions.
Standardized formats such as RLDS or LeRobot can also help organize sequential observations, actions, and metadata, although the final schema should match the target training pipeline.
Building Better Robot Policies With Roborax
Structuring human demonstrations is a critical step in transforming recorded behavior into useful learning signals. Consistent episode boundaries, synchronized observations, standardized action representations, contextual annotations, and rigorous quality checks help robotics teams develop datasets that are easier to scale and evaluate.
At Roborax, we recognize that high-quality Human Demonstration Data for Robot Learning must be designed around the target task, robot embodiment, and policy objectives. From data collection planning to annotation and dataset validation, a systematic approach helps teams build a stronger foundation for embodied AI and real-world robotic applications.
Ready to strengthen your robot learning pipeline? Connect with Roborax to explore robotics data collection and preparation strategies tailored to your training objectives.