AI Infrastructure Deployment Services Explained
Buying the right servers and GPUs is only half the battle. Once the hardware arrives, someone still has to rack it, wire it, power it, cool it, and get it talking to the rest of your environment without a hitch. Too many organizations discover this the hard way — after equipment is sitting in boxes with no clear plan for bringing it online. This is exactly where an experienced AI infrastructure provider earns its keep. The best providers don't just sell you gear; they own the entire journey from procurement to production, so your team can focus on the workloads instead of the wiring closet.
Common Deployment Pain Points
Even well-funded teams underestimate what it takes to stand up a GPU cluster. Rack design is often the first stumbling block — high-density AI servers draw far more power per rack unit than traditional compute, which means standard rack layouts and PDUs frequently don't cut it. Power and cooling come next: a handful of misconfigured racks can trip breakers, create hot spots, or force you into costly retrofits mid-project. Networking is its own challenge, since GPU clusters depend on low-latency fabric design, proper cable management, and switch configurations that traditional IT teams may not have tuned before.
This is why so many businesses turn to end-to-end deployment services rather than trying to coordinate electricians, network engineers, and hardware vendors themselves. A single accountable partner can sequence these dependencies correctly the first time, avoiding the rework that eats budgets and timelines.
For teams that want a deeper technical grounding, the ASHRAE data center thermal guidelines are a widely referenced industry standard for planning cooling and airflow in high-density environments — useful context even if your deployment partner handles the implementation.
Hardware Sourcing as Part of Deployment
Deployment doesn't start when boxes arrive on the loading dock — it starts with sourcing the right hardware for your workload and timeline. An AI infrastructure provider that's also involved in procurement can match GPU models, networking gear, and storage to your actual performance requirements, rather than leaving you to guess at compatibility after the fact.
This matters because GPU availability, firmware versions, and generational compatibility all affect how smoothly a cluster comes together. Providers with direct vendor relationships can browse the NVIDIA hardware catalog to identify configurations that are validated for your intended use case, whether that's large-scale training, inference at the edge, or a hybrid mix of both. Sourcing and deployment working together also shortens lead times, since procurement decisions are made with installation logistics — rack space, power budgets, network topology — already in mind, instead of treating hardware selection and physical rollout as two disconnected projects.
Reducing Downtime and Total Cost of Ownership
The real cost of a poorly executed deployment isn't just the install itself — it's the downtime, troubleshooting, and rework that follow. A fragmented approach, where hardware, networking, and facilities are handled by different vendors with no shared accountability, tends to produce exactly that kind of friction.
A full-service partner changes the equation. When one team designs the rack layout, configures the network, validates the power and cooling plan, and stands behind the result, issues get caught before they become outages. That single point of accountability also simplifies troubleshooting later, since there's no finger-pointing between vendors when something goes wrong.
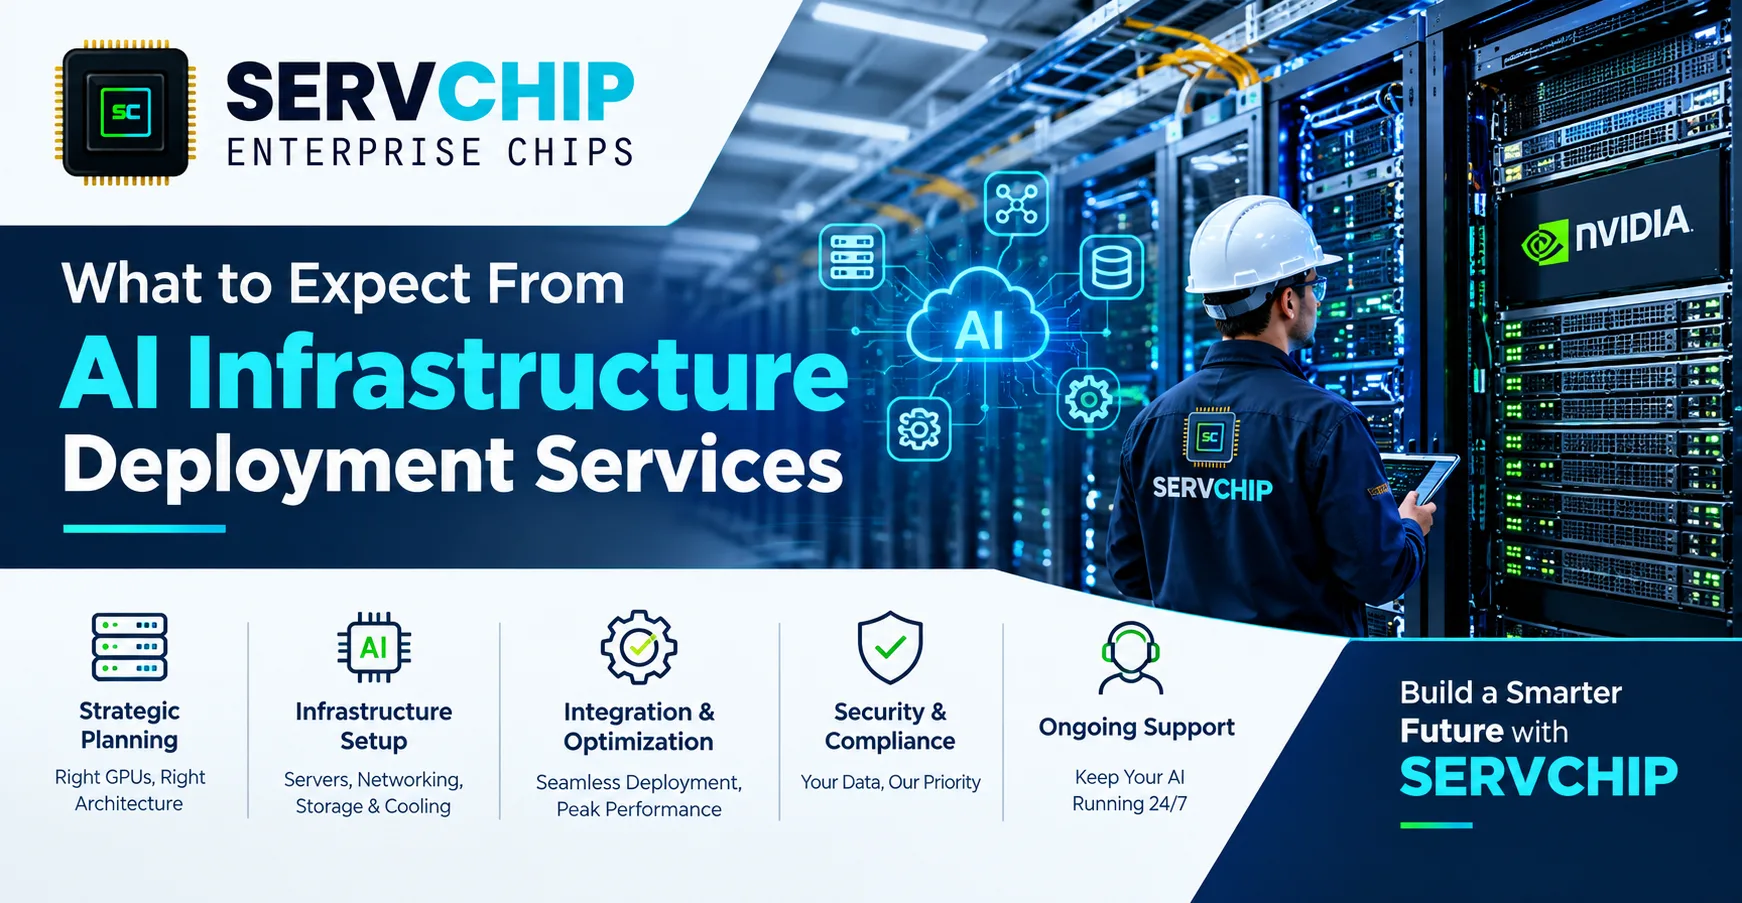
This is the core value proposition behind Servchip's AI infrastructure provider services: reducing the operational risk and hidden costs that come from stitching together multiple vendors. Lower downtime translates directly into a lower total cost of ownership, since idle GPU capacity — whether from delayed deployment or unplanned outages — is one of the most expensive line items in any AI infrastructure budget. Ongoing support after go-live further protects that investment by catching configuration drift and performance issues early.
Scoping Your Deployment Project
Every deployment is different, and the scoping conversation is where the details that matter most get surfaced — rack density targets, expected GPU count, power availability at your facility, and whether you're deploying on-prem, in a colocation facility, or across a hybrid setup. Getting these specifics right up front prevents the kind of mid-project surprises that stall timelines.
If you're planning a deployment, it's worth having that conversation early rather than after hardware has already shipped. The best next step is to talk to a deployment specialist who can walk through your requirements, flag potential constraints, and outline a realistic timeline before you commit to a configuration.
Conclusion
Standing up AI infrastructure involves far more than unboxing servers. Rack design, power and cooling planning, network configuration, and ongoing support all have to come together correctly — and the margin for error shrinks as cluster density increases. Working with a seasoned AI infrastructure provider means these pieces are handled by people who've solved these problems before, which helps prevent the costly delays and downtime that come from a disjointed, do-it-yourself approach. Professional deployment services aren't an added expense so much as insurance against the far greater cost of getting it wrong.
FAQs
What is included in AI infrastructure deployment services? Typically, these services cover rack and power planning, physical installation, networking and cabling, hardware configuration, testing and validation, and often ongoing monitoring or support once systems are live.
How long does a typical GPU cluster deployment take? Timelines vary with scale and site readiness, but small to mid-sized deployments often take a few weeks, while larger or hybrid rollouts can take longer depending on power, cooling, and networking prerequisites.
Do deployment services include ongoing maintenance? Many providers offer maintenance and support packages after initial deployment, covering monitoring, firmware updates, and troubleshooting to keep clusters running reliably.
What cooling requirements matter for dense GPU racks? High-density GPU racks generate significantly more heat than traditional servers, so airflow management, cooling capacity, and rack placement all need to be planned specifically for that thermal load.
Can deployment services be customized for hybrid or on-prem setups? Yes — a good provider will tailor the deployment plan to your environment, whether that's fully on-prem, colocation, cloud-hybrid, or a phased mix of the three.